Loading Project Media
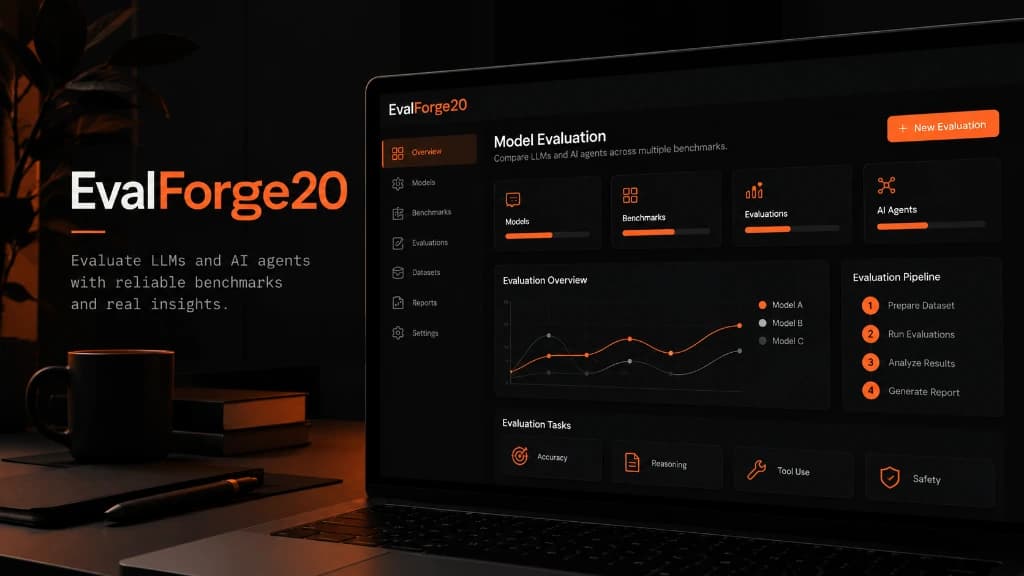
(Overview)
Anopen-source,local-firstevaluationplatformforbenchmarking,comparing,andimprovingAIsystemswithreproducibleexperiments.Designedtoevaluatelanguagemodelsandagentsagainstexplicittasks,datasets,andobjectivemetrics.
(Architecture)
ArchitectedasanextensibleevaluationrunnersupportinglocalmodelsviaOllamaandcloudmodelAPIs.Theplatformcoordinatestaskdatasets,standardizedprompttemplates,andmetricevaluatorstogeneratereproduciblebenchmarkscores.
(Engineering)
BuiltwithPythonandFastAPIbackendservicessupportingconcurrenttestsuiteexecution,responsecaching,structuredmetricscoring(accuracy,hallucinationdetection,latency),andclearmarkdownandJSONexportformodelcomparisons.
- 01
Architectedthemodularevaluationengineforrunningreproduciblebenchmarkexperiments.
- 02
Implementedconnectorpipelinesforlocalinference(Ollama)andcloudmodelendpoints.
- 03
Engineeredevaluationmetricsforaccuracy,outputconsistency,andresponselatency.
- 04
Createdstructuredexperimentloggingandcomparativevisualizationexports.
Built with
PythonFastAPILocal LLMsOllamaBenchmarkingEvaluation Pipelines
Explore this project
Inspect the live deployment or browse the repository code.
Haveaprojectinmind?
praveenlk41@gmail.com